Meta’s revised Commercial Terms take effect on 30 October 2026, and they carry a clause the version they replace did not. A business that uses Meta’s products authorises Meta to point automated software at that business’s own websites, and authorises Meta to use what it finds there to train Meta’s products.
There is nothing to sign. Acceptance is by continued use: post to a Facebook Page on 31 October and you have agreed. There is no partial opt-out, and as of this week no opt-out at all short of stopping business use of Meta’s products.
What the new clause says
The clause sits in Section 1 of the Commercial Terms, a section retitled from “Licences” to “Licences and rights you provide Meta”. In full:
“You authorize us (or any entity acting on our behalf) to use automated software (such as web scrapers, bots, robots, spiders, crawlers, and user agents) and create test credentials to access, index, cache, analyze, collect, retrieve, or crawl the domains, web pages, or URLs (and any content available through them) that are associated with your products or services, or that are made available through your or users’ use of Meta Company Products and services, and to periodically pull updates from such domains, web pages, or URLs. Meta may use any content from such domains, web pages, or URLs to provide, develop, improve, research, train, and maintain the integrity of, the Meta Company Products, services, and features provided under these Commercial Terms and any other applicable supplemental terms.”
How that quotation reached this article. Meta’s legal pages disallow automated fetching, so the wording could not be read from facebook.com during this run. It comes from two independent renderings: Nieman Lab (Andrew Deck and Hanaa’ Tameez, 15 October 2026) and PPC Land (Luis Rijo, 16 October 2026). They agree word for word and differ exactly as two readings of different language editions should — Nieman Lab has “authorize” and “analyze”, PPC Land has “authorise” and says it read the UK edition. That corroborates the transcription, not the document.
How a business accepts it, and what refusing costs
Acceptance is passive. PPC Land quotes Section 7: “By continuing any access or use of any Meta Company Products for business or commercial purposes after any notice of an update to these Commercial Terms, you agree to be bound by them.” Nieman Lab reports that Meta notified business users in early October through a blog post and in Meta Business Suite.
The scope is business use, not advertising: the examples PPC Land lists include listing products, using a product catalogue, and using any business product such as Ads Manager or Meta Business Suite. Search Engine Journal (Matt G. Southern, 16 October 2026) puts it in its headline — the grant reaches businesses that never buy an ad. PPC Land’s own follow-up of 17 October 2026 frames it more narrowly, as advertisers’ websites; two reports by the same author a day apart describe the scope differently, and the narrower framing is the one the clause’s text does not support.
On refusal the renderings diverge by one word. Nieman Lab quotes “please stop all access or use of our Products for business or commercial purposes”; PPC Land says “please stop” is the March 2024 wording and the new version reads “you may stop”. This article cannot settle which is on the page today, and both point the same way: Nieman Lab reports “there is currently no option for business accounts to opt out of these new terms ahead of October 30”.
What Meta’s own crawler documentation says
Meta publishes a page listing its web crawlers and how to control them. Read live on 17 October 2026, it names five user-agent tokens, and its stated control is robots.txt: “We make it easy for site managers and content owners to indicate their preferences by using industry-standard practices like robots.txt rather than non-standard formats like NoAI tags.”
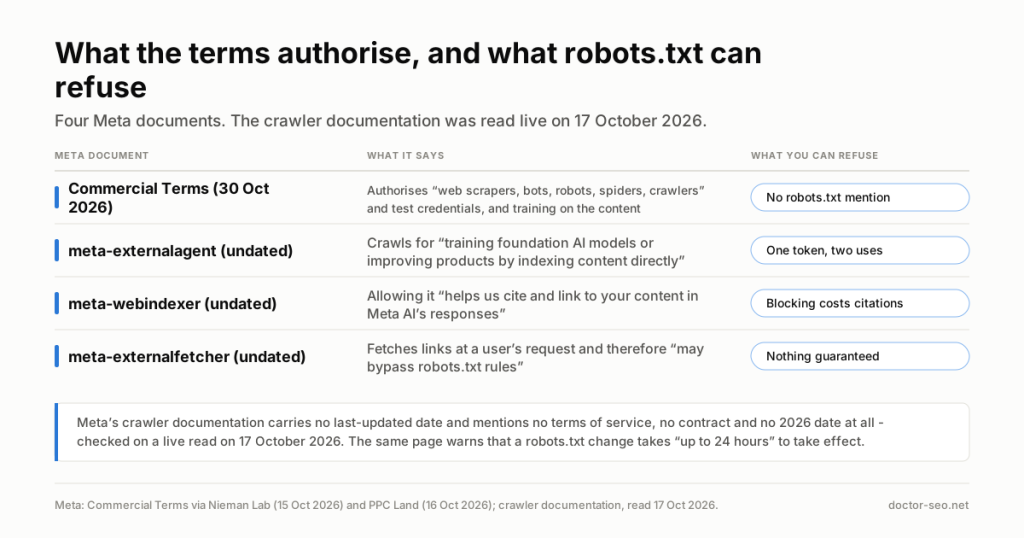
Asked explicitly, that page mentions no terms of service, no contract and no 2026 date anywhere, and carries no last-updated stamp. The Commercial Terms, on both renderings above, do not mention robots.txt. So the two Meta documents governing the same behaviour — what Meta’s software may take from your site, and what you may do about it — do not reference each other in either direction.
The tokens do not map onto the purposes a site owner might want to refuse. Meta-ExternalAgent “crawls the web for use cases such as training foundation AI models or improving products by indexing content directly” — one token covering two purposes a publisher would weigh separately. A single Disallow refuses both, and there is no documented way to refuse the training and keep the indexing.
Meta-WebIndexer “navigates the web to improve Meta AI search result quality for users”, and Meta’s own sentence prices the decision: “Allowing Meta-WebIndexer in your robots.txt file helps us cite and link to your content in Meta AI’s responses.” Blocking it is the cleanest refusal available and it costs exactly what an SEO wants from an AI surface. The same trade-off, for another company’s crawlers, is the subject of Claude’s three crawlers and your robots.txt. And two of the five tokens are documented as able to ignore the file Meta recommends: Meta-ExternalFetcher “may bypass robots.txt rules”, and FacebookExternalHit “might bypass robots.txt when performing security or integrity checks”.
What Meta said, and what three lawyers said
Meta disputes the reading. Andy Stone, its communications head, replied on X on 16 October 2026. That post cannot be fetched here — x.com disallows automated retrieval — so it arrives through trade reports carrying different amounts of it. The fullest is PPC Land’s: “This is false. There’s no change to how Meta uses web crawlers. As always, content owners can use robots.txt flags to indicate their preferences. This update is designed to make sure we’re able to pull accurate information about products for sale on third-party websites when making on-platform ad and content recommendations, not about scraping news sites.” PPC Land’s follow-up a day later quotes only the last sentence, dropping “This is false” and the robots.txt line. A Meta spokesperson separately told Nieman Lab the update merely consolidates crawling language previously scattered across different terms, adding that “content owners can still manage how their content is accessed by using robots.txt”. Meta declined to answer Nieman Lab’s list of questions, and declined to say whether the test credentials would bypass paywalls.
Nieman Lab asked three lawyers to read the terms. Matt Topic, of Loevy & Loevy, called it “a remarkable provision to bury in [the] terms of service” and added: “It’s not clear whether a court would enforce this, but publishers should assume that it would be enforceable.” Benjamin Sobel, of the University of Wisconsin, put the bind plainly: “If you want to use the Meta products that require acceptance of the commercial terms, you have to also acquiesce to the scraping and crawling permissions exacted in those terms.” James Grimmelmann of Cornell read it as permission to train on any content from a publisher’s site. Nieman Lab adds, unattributed, that the wording “creates an opening for Meta to argue its commercial terms supersede other blocking instructions”. Nobody has tested that.
What this changes in practice
Technically, possibly nothing. Stone’s claim that there is no change to how Meta uses web crawlers is not contradicted by anything on the record: the crawler documentation carries no 2026 date, so there is no documented change in behaviour to point at.
Contractually, the change is the point. Before 30 October, a site owner who blocks meta-externalagent is refusing a request. After 30 October, if the clause binds, that owner has also granted permission — two different things expressed in the same file. Nothing in Meta’s documentation says a robots.txt rule withdraws the grant; nothing in the terms says the grant overrides the file. That is not a contradiction between the documents, it is a question neither answers. For a reader doing technical SEO the consequence is narrower than the headlines and more irritating: the decision now has a date on it, the granularity available is worse than the granularity of the grant, and the cleanest refusal costs visibility in an AI answer surface.
What to do before 30 October
Start by reading what you already publish:
curl -s https://example.com/robots.txt | grep -iE 'meta-external(agent|ads|fetcher)|meta-webindexer|facebookexternalhit'An empty result means you address none of Meta’s five tokens and allow all of them by default. Then decide each separately, because they do different things:
| Token | What Meta says it does | What blocking it costs |
|---|---|---|
meta-externalagent |
Training foundation AI models, or indexing content to improve products | Both at once — one token, no split |
meta-webindexer |
Improves Meta AI search quality; allowing it “helps us cite and link to your content” | Citations and links in Meta AI answers |
meta-externalads |
Improving advertising and other business products | Not stated by Meta |
meta-externalfetcher |
Fetches links at a user’s request; “may bypass robots.txt rules” | Possibly nothing — the rule may not be honoured |
facebookexternalhit |
Builds the preview card when a link is shared | Your link previews on Facebook, Instagram and Messenger |
- Keep a dated copy of your robots.txt as it stands before 30 October. A record of what you permitted and when is cheap now and impossible to reconstruct later.
- Make any change by 28 October, not the 29th. Meta’s page says to “allow up to 24 hours for changes to
robots.txtto take effect because crawlers may cache the contents ofrobots.txtfor up to 24 hours”, so a file edited the day before may not be in force when the terms are. - Do not assume blocking settles it. On the documented record a
Disallowis a technical preference and the clause is a contractual permission, and no published source says the first withdraws the second.
Where the industry genuinely disagrees
Whether a contractual grant changes what robots.txt achieves. One camp says a crawler that honours a Disallow does not take the content whatever a contract permits, and Meta itself keeps pointing owners at the file. The other says a permission you granted is not undone by a preference you express, and Nieman Lab’s lawyers say the wording gives Meta an opening to argue exactly that. No court has ruled on this clause, and Meta has published nothing reconciling the two documents.
Whether blocking a mixed-use token refuses the purpose you object to. One camp says a token is the only granularity the standard offers, so blocking it refuses everything it does. The other says being forced to give up indexing in order to refuse training is a bundle rather than consent, and that no refusal of training alone is available. No measurement exists either way.
Whether sites should block AI crawlers at all. This site holds no position and takes none here. Cloudflare Radar’s parse of around 4,000 robots.txt files (31 August 2026) found training bots blocked two to three times more often than allowed while answering bots were net-allowed — which describes what publishers do, not whether they are right, and the citation side of that trade-off is where the cost shows up.
Whether an executive’s description of behaviour is evidence about behaviour. Stone says there is no change to how Meta uses web crawlers — a statement about the conduct of the party making it, on a platform this site cannot read directly, and Meta publishes no crawler changelog to check it against. The related question, live for every agentic surface, is whether a fetch made at a user’s request should be governed by robots.txt at all; Meta documents meta-externalfetcher as able to bypass it, and nobody has measured what such a fetch presents.
What I think
I will defend one claim and no more: the two Meta documents governing this do not meet. The Commercial Terms authorise automated collection and training and, on both available renderings, do not mention robots.txt. The crawler documentation offers robots.txt as the control and, verified on a live read on 17 October 2026, mentions no terms, no contract and no 2026 date. Meta’s spokesperson and its communications head both point site owners at a file the governing document does not discuss. Anyone can check that in five minutes.
What I will not say is whether you have lost anything. I do not know whether a court would hold the clause enforceable — one of the three lawyers said plainly that it is not clear. I will not tell you blocking is futile, because no source says the grant defeats the file, nor that blocking is sufficient, because no source says it withdraws the grant. Both sentences are being written this week by people who know neither. The honest reading is duller than the headlines: a date has been attached to a decision most site owners were deferring, and the controls available are coarser than the permission being granted. That is worth two hours of somebody’s week and it is not worth a crisis.
What is still unknown
Whether the clause is enforceable. Whether “associated with your products or services” reaches a whole domain or only product pages — PPC Land notes the terms do not define it. Whether the test credentials would bypass paywalls; Meta declined to answer that. How many sites are affected: no party has published a count. And whether crawler behaviour changes at all, which Meta says it will not and which no outside party can measure.
Sources
- Meta, Commercial Terms, effective 30 October 2026. The page disallows automated fetching and could not be read during this run; quoted via the two renderings below.
- Meta, Meta Web Crawlers developer documentation. Read live 17 October 2026; carries no last-updated date.
- Andrew Deck and Hanaa’ Tameez, “Meta’s new commercial terms will allow the scraping of news sites, legal experts say”, Nieman Lab, 15 October 2026.
- Luis Rijo, “Meta’s new terms let it crawl business websites to train AI from Oct 30”, PPC Land, 16 October 2026.
- Luis Rijo, “Meta grants itself the right to crawl advertisers’ websites for AI”, PPC Land, 17 October 2026.
- Matt G. Southern, “Meta’s New Terms Expand Crawling Rights Beyond Advertisers”, Search Engine Journal, 16 October 2026.
- Andy Stone, post on X, 16 October 2026. Not fetchable in this environment; quoted from PPC Land’s rendering of 16 October 2026.
- Cloudflare Radar, robots.txt analysis of approximately 4,000 domains, 31 August 2026.